
How to Troubleshoot Slow Applications
 Oliver Ripka
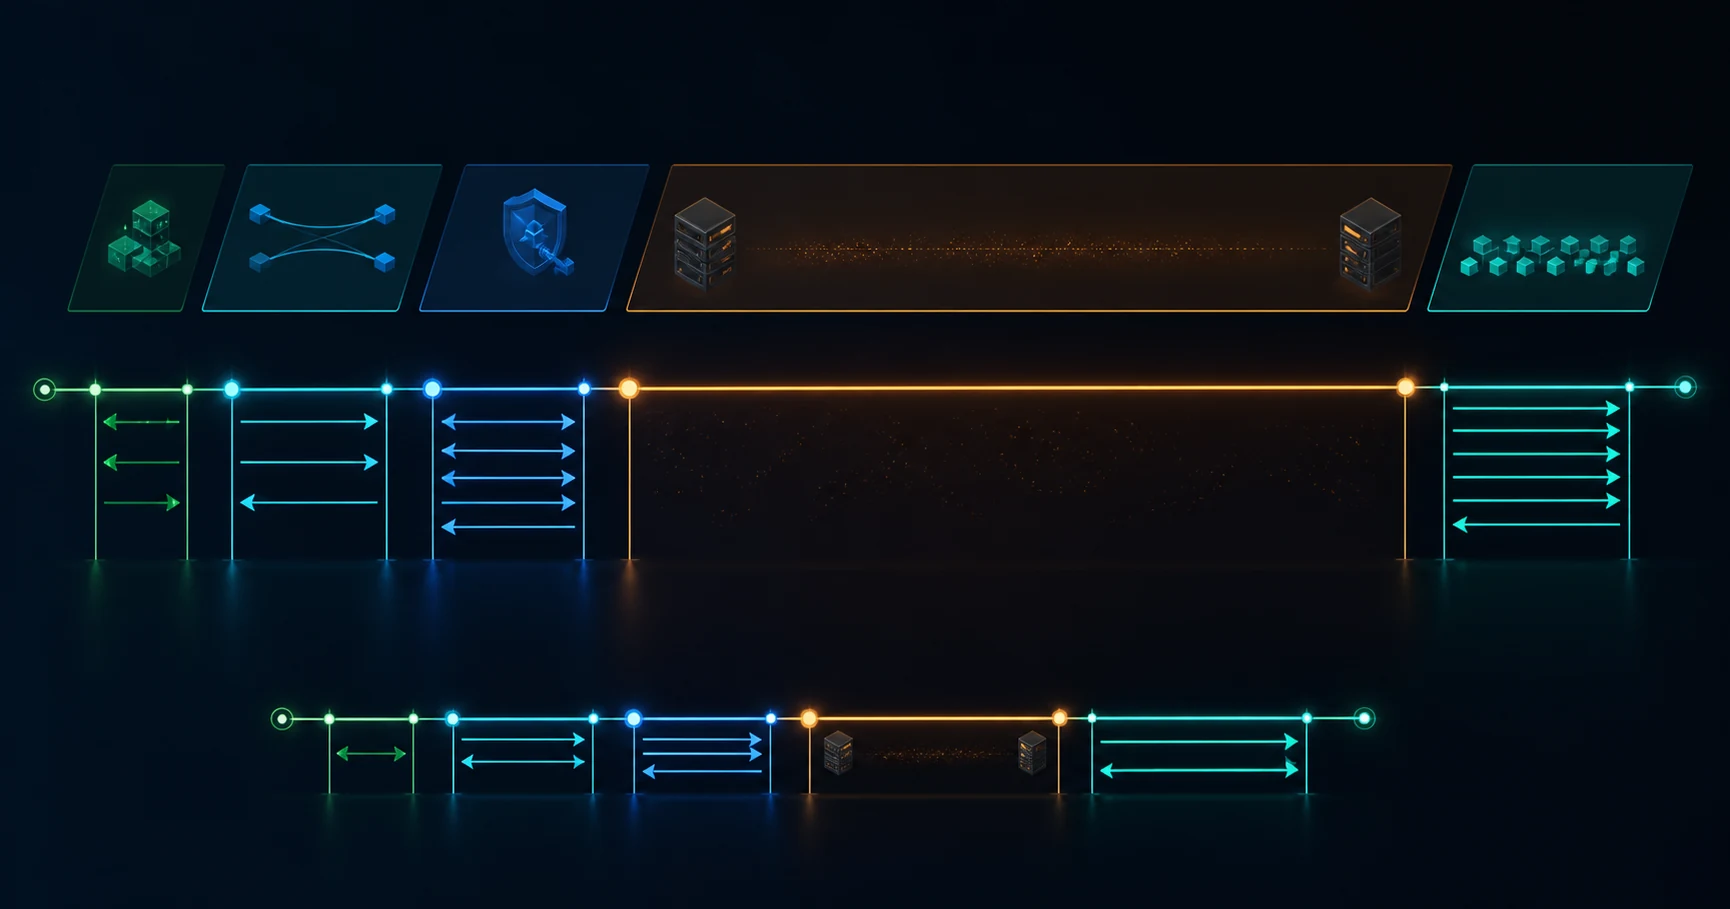
To troubleshoot a slow application, first define what "slow" means and who is affected, then check each layer with the cheapest data you already have: browser developer tools, ping and mtr, server metrics, and APM traces. Take a packet capture when those sources disagree, when ownership is disputed between teams, or when the delay sits somewhere no log can see. Capturing first, before the problem is scoped, usually produces a large file that answers the wrong question.
This guide covers the whole troubleshooting path. When you reach the point where packets are needed, the companion guide on troubleshooting slow applications with packet captures explains how to build the transaction timeline from a trace.
The checklist at a glance
| Layer | Question | Cheapest first data | Escalate with |
|---|---|---|---|
| Definition | What exactly is slow, and compared with what? | User report, screenshot, timestamp | A measured baseline |
| Scope | One user or all, one site or all, since when? | Ticket history, monitoring dashboards | Synthetic tests from several locations |
| Client | Is the endpoint itself the bottleneck? | Browser devtools, task manager | Endpoint profiling |
| DNS | Does name resolution add delay or fail? | dig, nslookup, devtools timing | Resolver logs, capture at the client |
| Network path | Is there latency, loss, or a bad hop? | ping, mtr, interface counters | Packet capture at two points |
| Server | Is the host short of CPU, memory, disk, or threads? | Host metrics, web server logs | Profiler, application logs |
| Dependencies | Is a database, API, or auth service slow? | APM traces, dependency dashboards | Captures between tiers |
Work top to bottom. Each row should rule a layer out or justify a deeper look.
Step 1: define "slow"
"The application is slow" can mean several different things:
- a page or screen takes too long to load
- one specific action, such as search or save, is slow
- the application hangs and then times out
- throughput is low on uploads or downloads
- it is slow at certain times of day only
Ask for one concrete example: the action, the time, the user or machine, and how long it took compared with normal. "Saving an invoice took 12 seconds at 14:05, it normally takes under 1 second" is something you can test. A vague report should be turned into a measurable one before anyone changes a configuration.
Step 2: scope the problem
Scope usually eliminates half the layers before any tool is opened.
- One user or many? A single affected user points to the client, their account, or their access path. Everyone affected points to shared infrastructure or the service.
- One site or all sites? If only one office or region is slow, look at that site's WAN link, proxy, VPN, or local resolver.
- One action or all actions? A single slow function often points to a specific query, API call, or dependency.
- Since when? Compare the start time with change records: deployments, certificate renewals, firewall rules, DNS changes, or capacity events.
- Constant or intermittent? Intermittent slowness needs data collected during the bad period, which affects where and when you capture.
Write the scope down. It becomes the filter for everything that follows.
Step 3: check the client
For web applications, open the browser developer tools on an affected machine and record the slow action in the Network panel. The timing breakdown for each request separates queueing, DNS lookup, connection setup, TLS, waiting for the first byte, and content download. That is often enough to point at the right layer within minutes.
Also check the endpoint itself:
- CPU or memory pressure on the machine
- security agents or proxies inspecting traffic
- a large page with many requests, scripts, or blocked resources
- a slow single request versus many sequential requests that add up
If the devtools timing shows most of the time is spent rendering or running scripts locally, the network and server are probably not the cause.
Step 4: check DNS
Name resolution is cheap to test and often overlooked:
dig app.example.test
dig @10.0.0.53 app.example.test
nslookup app.example.test
Look at the query time, whether the answer is correct, and whether different resolvers return different addresses. Slow or failing DNS can add seconds to the first request, especially when a client tries an unreachable resolver before falling back to the next one. If affected and unaffected users use different resolvers, compare them directly.
Step 5: check the network path
Basic path tools give you latency, loss, and a hop-by-hop picture:
ping -c 20 app.example.test
mtr -rwc 50 app.example.test
Useful readings:
- High or variable round-trip time to the service suggests path latency or congestion.
- Loss that persists to the final hop is more meaningful than loss at one intermediate hop, which may simply rate-limit ICMP.
- A detour through an unexpected region, VPN concentrator, or proxy explains latency that no server metric will show.
Also look at interface error and discard counters on switches, routers, and firewalls in the path. They are cheap to read and can confirm or rule out physical problems. Keep in mind that ICMP may be treated differently from application traffic, so a clean ping does not prove the application's TCP connections are healthy.
Step 6: check the server
If the client and path look normal, look at the host serving the application:
- CPU, memory, disk latency, and network interface utilization
- thread pools, connection pools, and worker counts
- web server or load balancer access logs with request duration
- error logs around the reported time
Request duration in the access log is especially useful. If the server logs the request as fast but the user saw it as slow, the delay is between them: in the network, a proxy, a load balancer, or the client. If the server logs it as slow, the investigation moves inward.
Step 7: check dependencies
Most modern applications wait on something else: a database, an internal API, an authentication service, a file share, or a third-party service. Application performance monitoring, distributed tracing, and database slow-query logs are the right tools here. A trace that shows 4.5 seconds inside one database call is far more direct than any packet capture taken at the user's laptop.
If you do not have APM, check the dependency's own metrics and logs for the same time window, and test the dependency directly from the application server.
When to take a packet capture
Packet captures are the right next step when:
- different teams' tools disagree about where the time goes
- the server reports fast responses but users see slow ones
- the problem involves TCP behavior such as retransmissions, resets, or small windows
- a proxy, firewall, load balancer, or WAN optimizer sits in the path and its logs are incomplete
- the application is third-party and you have no internal logs or traces
- you need evidence another team or vendor will accept
Where to capture
Pick the capture point based on the question:
- At the affected client to see exactly what the user experiences, including DNS and TLS.
- At the server or in front of it to see when requests arrive and when responses leave.
- On both sides of a middlebox to find out whether a proxy or firewall adds delay.
- At two points at once, with synchronized clocks, when ownership is disputed. One capture shows where delay appears. Two can show where it was introduced.
Capture a narrow window around a reproduced slow action, include both directions, and capture a fast example for comparison. The quick-start guide to analyzing a PCAP helps you orient in the resulting file in the first 15 minutes.
How to read the result
A packet trace can separate DNS, connection setup, TLS, server wait, and transfer time for a single transaction. It can show retransmissions, zero windows, and resets with exact frame numbers. It cannot tell you which line of server code was slow or which database query blocked, because that happens inside the host. The packet-capture troubleshooting guide walks through each stage and the common misreadings, and the TCP retransmission analysis guide covers loss in depth.
For a selected capture, PacketSafari Triage runs capture-wide checks and links each signal to its matching frames, and the Analyzer turns that Evidence Map into a Final Report with exact packet evidence and explicit coverage. It investigates the capture you give it after the fact. It does not replace APM, server metrics, or continuous monitoring, and it cannot see delay inside a host that never appears on the wire.
Next steps
- Write down the definition and scope of the slowness in one or two sentences.
- Collect the cheapest data for each layer: devtools timing, DNS lookups, ping and mtr, server request duration, and dependency traces.
- Rule layers in or out explicitly, and note which data supported each decision.
- If ownership is still unclear, capture a slow and a fast example at the right point, ideally two points.
- Report what the evidence proves, what it rules out, and which team owns the next check.